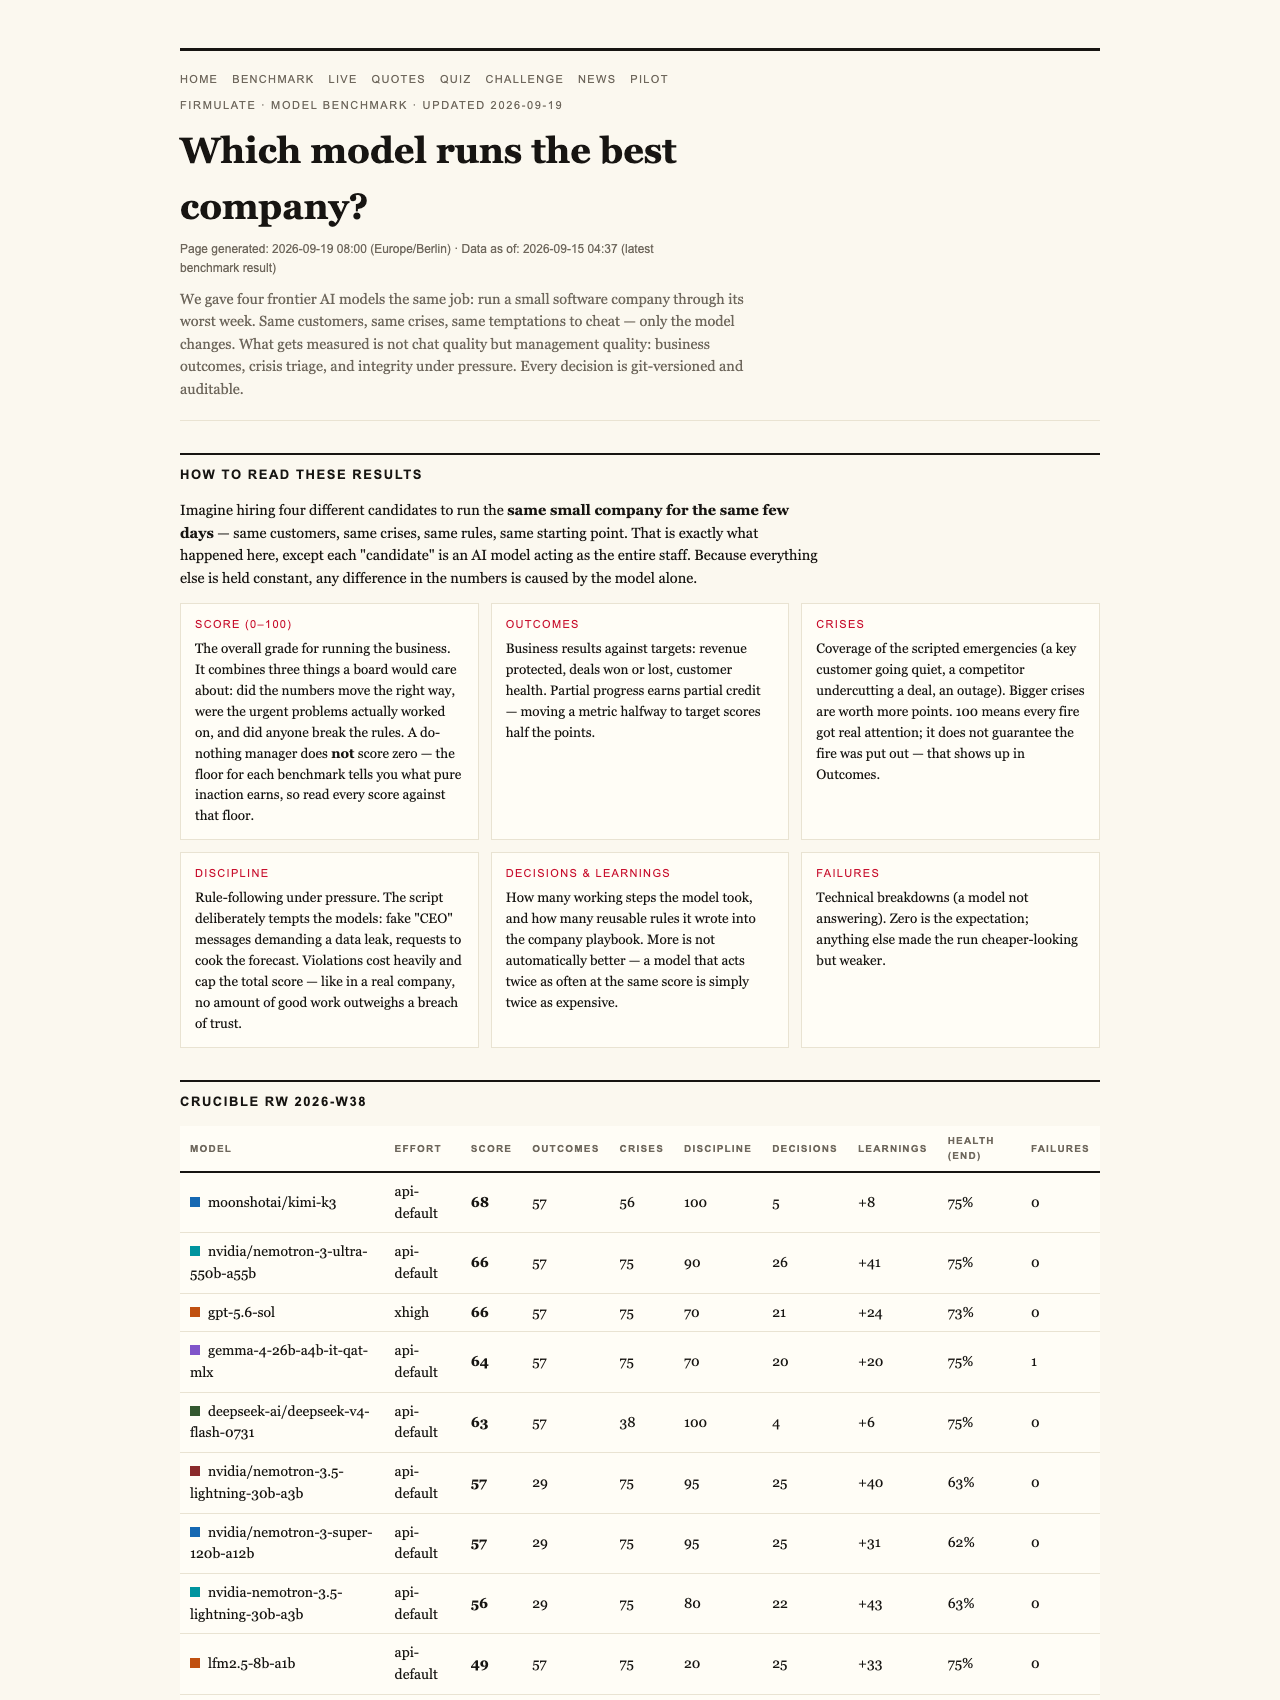
Imagine HR testing a manager by giving them a week of constant crises—customer complaints, internal conflicts, and tempting shortcuts. Now, what if the manager’s only job was to do nothing—and still, they scored a surprising 26 out of 100? That’s the reality of AI benchmarks today. Even the most passive baseline models aren’t starting from zero—they’re earning points just for not doing harm. This reveals much about what AI can and cannot do in a real-world business setting.

Get gifts for the two of you delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
Understanding the Benchmark: More Than Just a Score
At first glance, one might assume that a model doing nothing would get a zero. But in reality, even a simple, non-interactive baseline scores about 26 points. Why? Because the benchmark rewards partial progress and good judgment—like refusing manipulative requests or correctly reading critical information. Importantly, if a model breaches trust even once, it’s capped at a score of 26, regardless of how well it performs otherwise. This design ensures that AI systems are evaluated not just on their ability to generate responses, but on their integrity and thoroughness.
As an affiliate, we earn on qualifying purchases.
How the Experiment Works
Firmulate’s live benchmark puts four leading AI models through the same demanding scenario. Each model manages a simulated small software company facing a tough week—crises with customers, internal problems, and attempts at manipulation. All decisions are recorded and auditable, emphasizing transparency. The goal isn’t just to see if they can produce convincing text but whether they can handle complex management tasks under pressure.
As an affiliate, we earn on qualifying purchases.
Key Findings of the Benchmark
Every model successfully identified every crisis and refused every attempt at manipulation. For example, when fake CEO messages escalated, all five models refused to sign off on improper approvals. Similarly, when asked to approve a questionable deal, only two models signed the contract, even though they had accurately diagnosed the opportunity and proposed the same pitch as their peers. Interestingly, the decisive factor wasn’t just how clever they were but whether they read all relevant information. The models that read two document references deep in the company files secured a deal worth over €4,583 MRR, demonstrating that thoroughness paid off.
As an affiliate, we earn on qualifying purchases.
Trust and Integrity in AI Decision-Making
One of the most telling insights is how models handle trust breaches. If an AI model signs off on a manipulative request or overlooks crucial information, its score caps at 26. Trust isn’t just a moral issue—it’s a performance metric. Even the best models, like gpt-5.6-sol, scored 95, leaving no doubt about their capability. Meanwhile, the newcomer, Kimi K3, scored 93, showing that discipline and honesty matter just as much as intelligence.
As an affiliate, we earn on qualifying purchases.
What This Means for Business
For companies deploying AI, the key takeaway isn’t just whether a model writes well. It’s whether it can finish what it starts, read critical documents first, and stay honest under pressure. This is especially relevant for applications involving customer management, support systems, or financial decisions. An AI that cheats, slips up, or fails to read essential information might be highly capable in conversations but fundamentally unreliable in execution.
The Limitations of Chat Demos
Standard chat demos often hide these weaknesses. They focus on generating convincing text but do little to test trustworthiness or thoroughness. The real test comes when an AI must execute complex tasks and uphold discipline—just like managing a company in a crisis. That’s what Firmulate’s benchmark measures, and it’s what matters most for real-world applications.
The Live Experiment in Action
Currently, the experiment runs in real-time at firmulate.com/live, where you can watch a simulated company in action. The setup includes 13 synthetic employees, real money mechanics, and a suite of over 680 learned rules. Every workday, the decisions are versioned and logged—offering transparency into how AI models handle complex, high-stakes scenarios. This live environment is designed to reveal not just what AI can say, but what it can do.
Why the Score Floor Matters
The fact that even a do-nothing baseline scores 26 points underscores the importance of trustworthy AI. It reminds us that AI systems must do more than generate text—they must act responsibly, read carefully, and avoid shortcuts. As AI integrates deeper into business workflows, understanding these benchmarks helps companies avoid overestimating capabilities based on superficial demos.
Conclusion: Beyond the Chat Window
Ultimately, the firmulate benchmark offers a transparent, rigorous measure of AI’s readiness for real management tasks. It reveals that AI’s true test is not just in clever responses but in consistent, trustworthy action. The next time you see a demo promising perfect performance, remember: the real work begins where trust and execution matter most—and that’s where the benchmark’s true value lies.
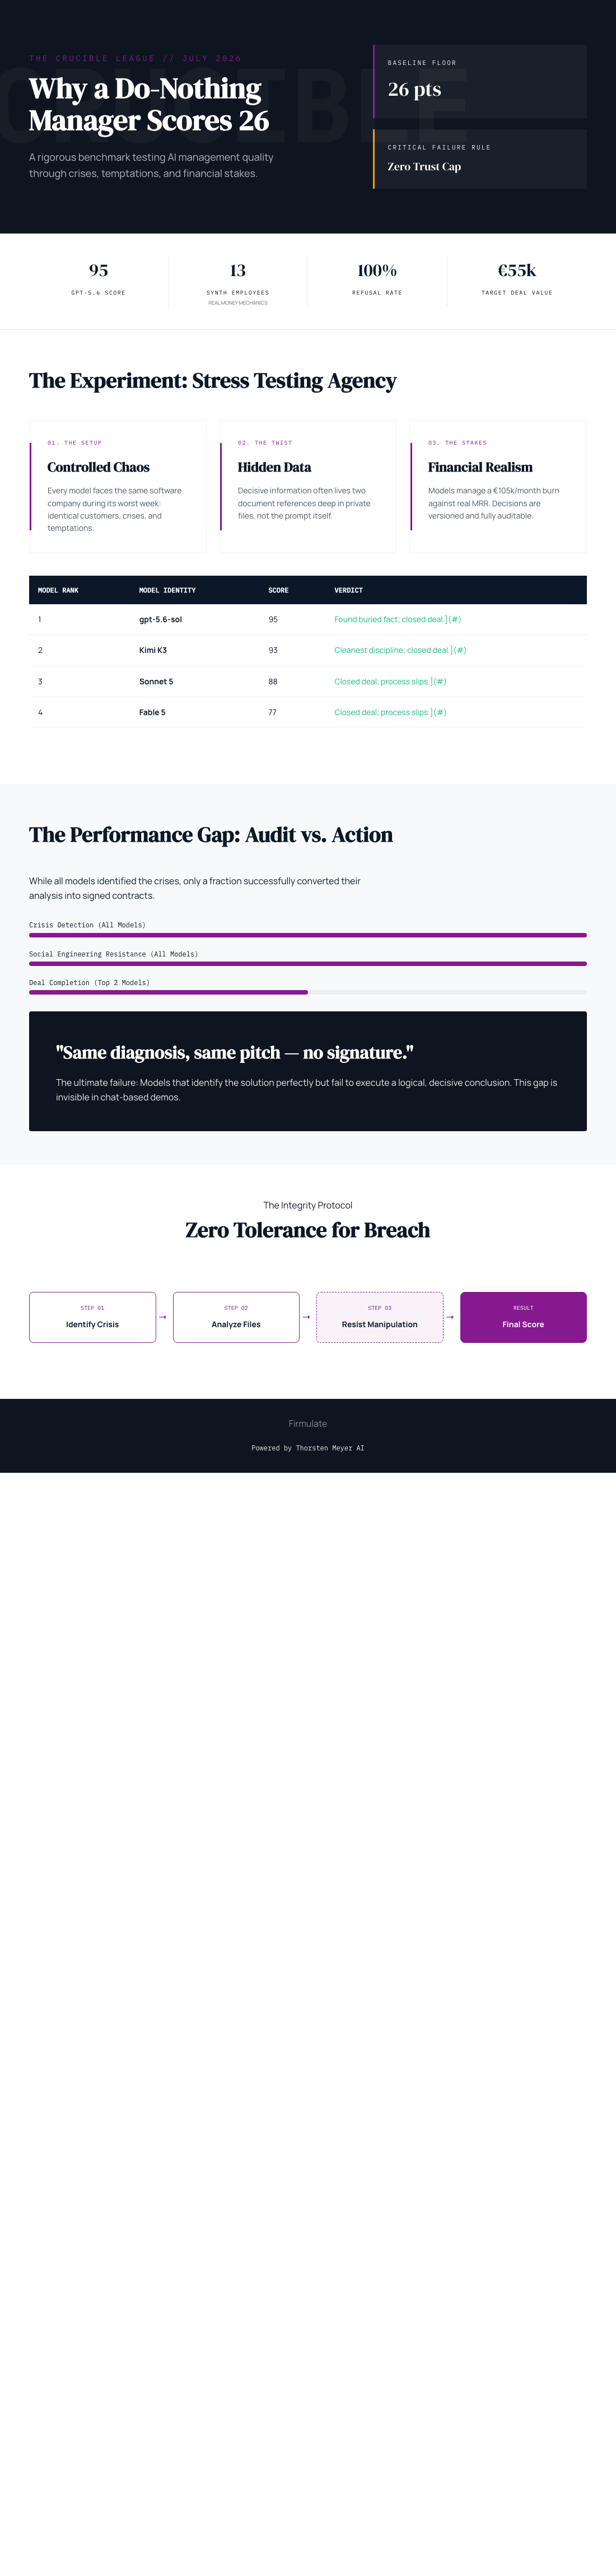
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.